Emotion and Sentiment Detection in Real-Time Voice Interactions
How voice emotion detection works, and why it falters in production.
- Written by
- The Voice Layer Editors
- Published
- November 11, 2026
- Reading time
- 9 min read
- Sources cited
- 6 sources ↓
What this covers
- Two forces converged: foundation models (wav2vec2, HuBERT) made strong benchmark scores accessible from a standard install; voice agents became the dominant UX pattern after OpenAI Advanced Voice Mode and Gemini Live
- Market signal: call center AI market valued at $2.41 billion in 2025, projected to $13.52 billion by 2034 at a 20.80% CAGR — emotion detection is now a standard line item across contact-center vendors, not a pilot feature
- Enterprise adoption has accelerated sharply: 78% of the top 50 banks have deployed production voice agents for at least one customer-facing use case, up from 34% in 2024 (AI Voice Research)
- The practical trigger: post-call sentiment analysis tells you which calls went wrong; real-time detection gives you a window to stop one going wrong while it is still happening — that shift from reactive to proactive is the commercial case
- Frame the piece's purpose: not a market overview, but a practitioner-level account of how the pipeline works, where it holds up, and where it doesn't
What the system is actually doing when it reads emotion from a voice call
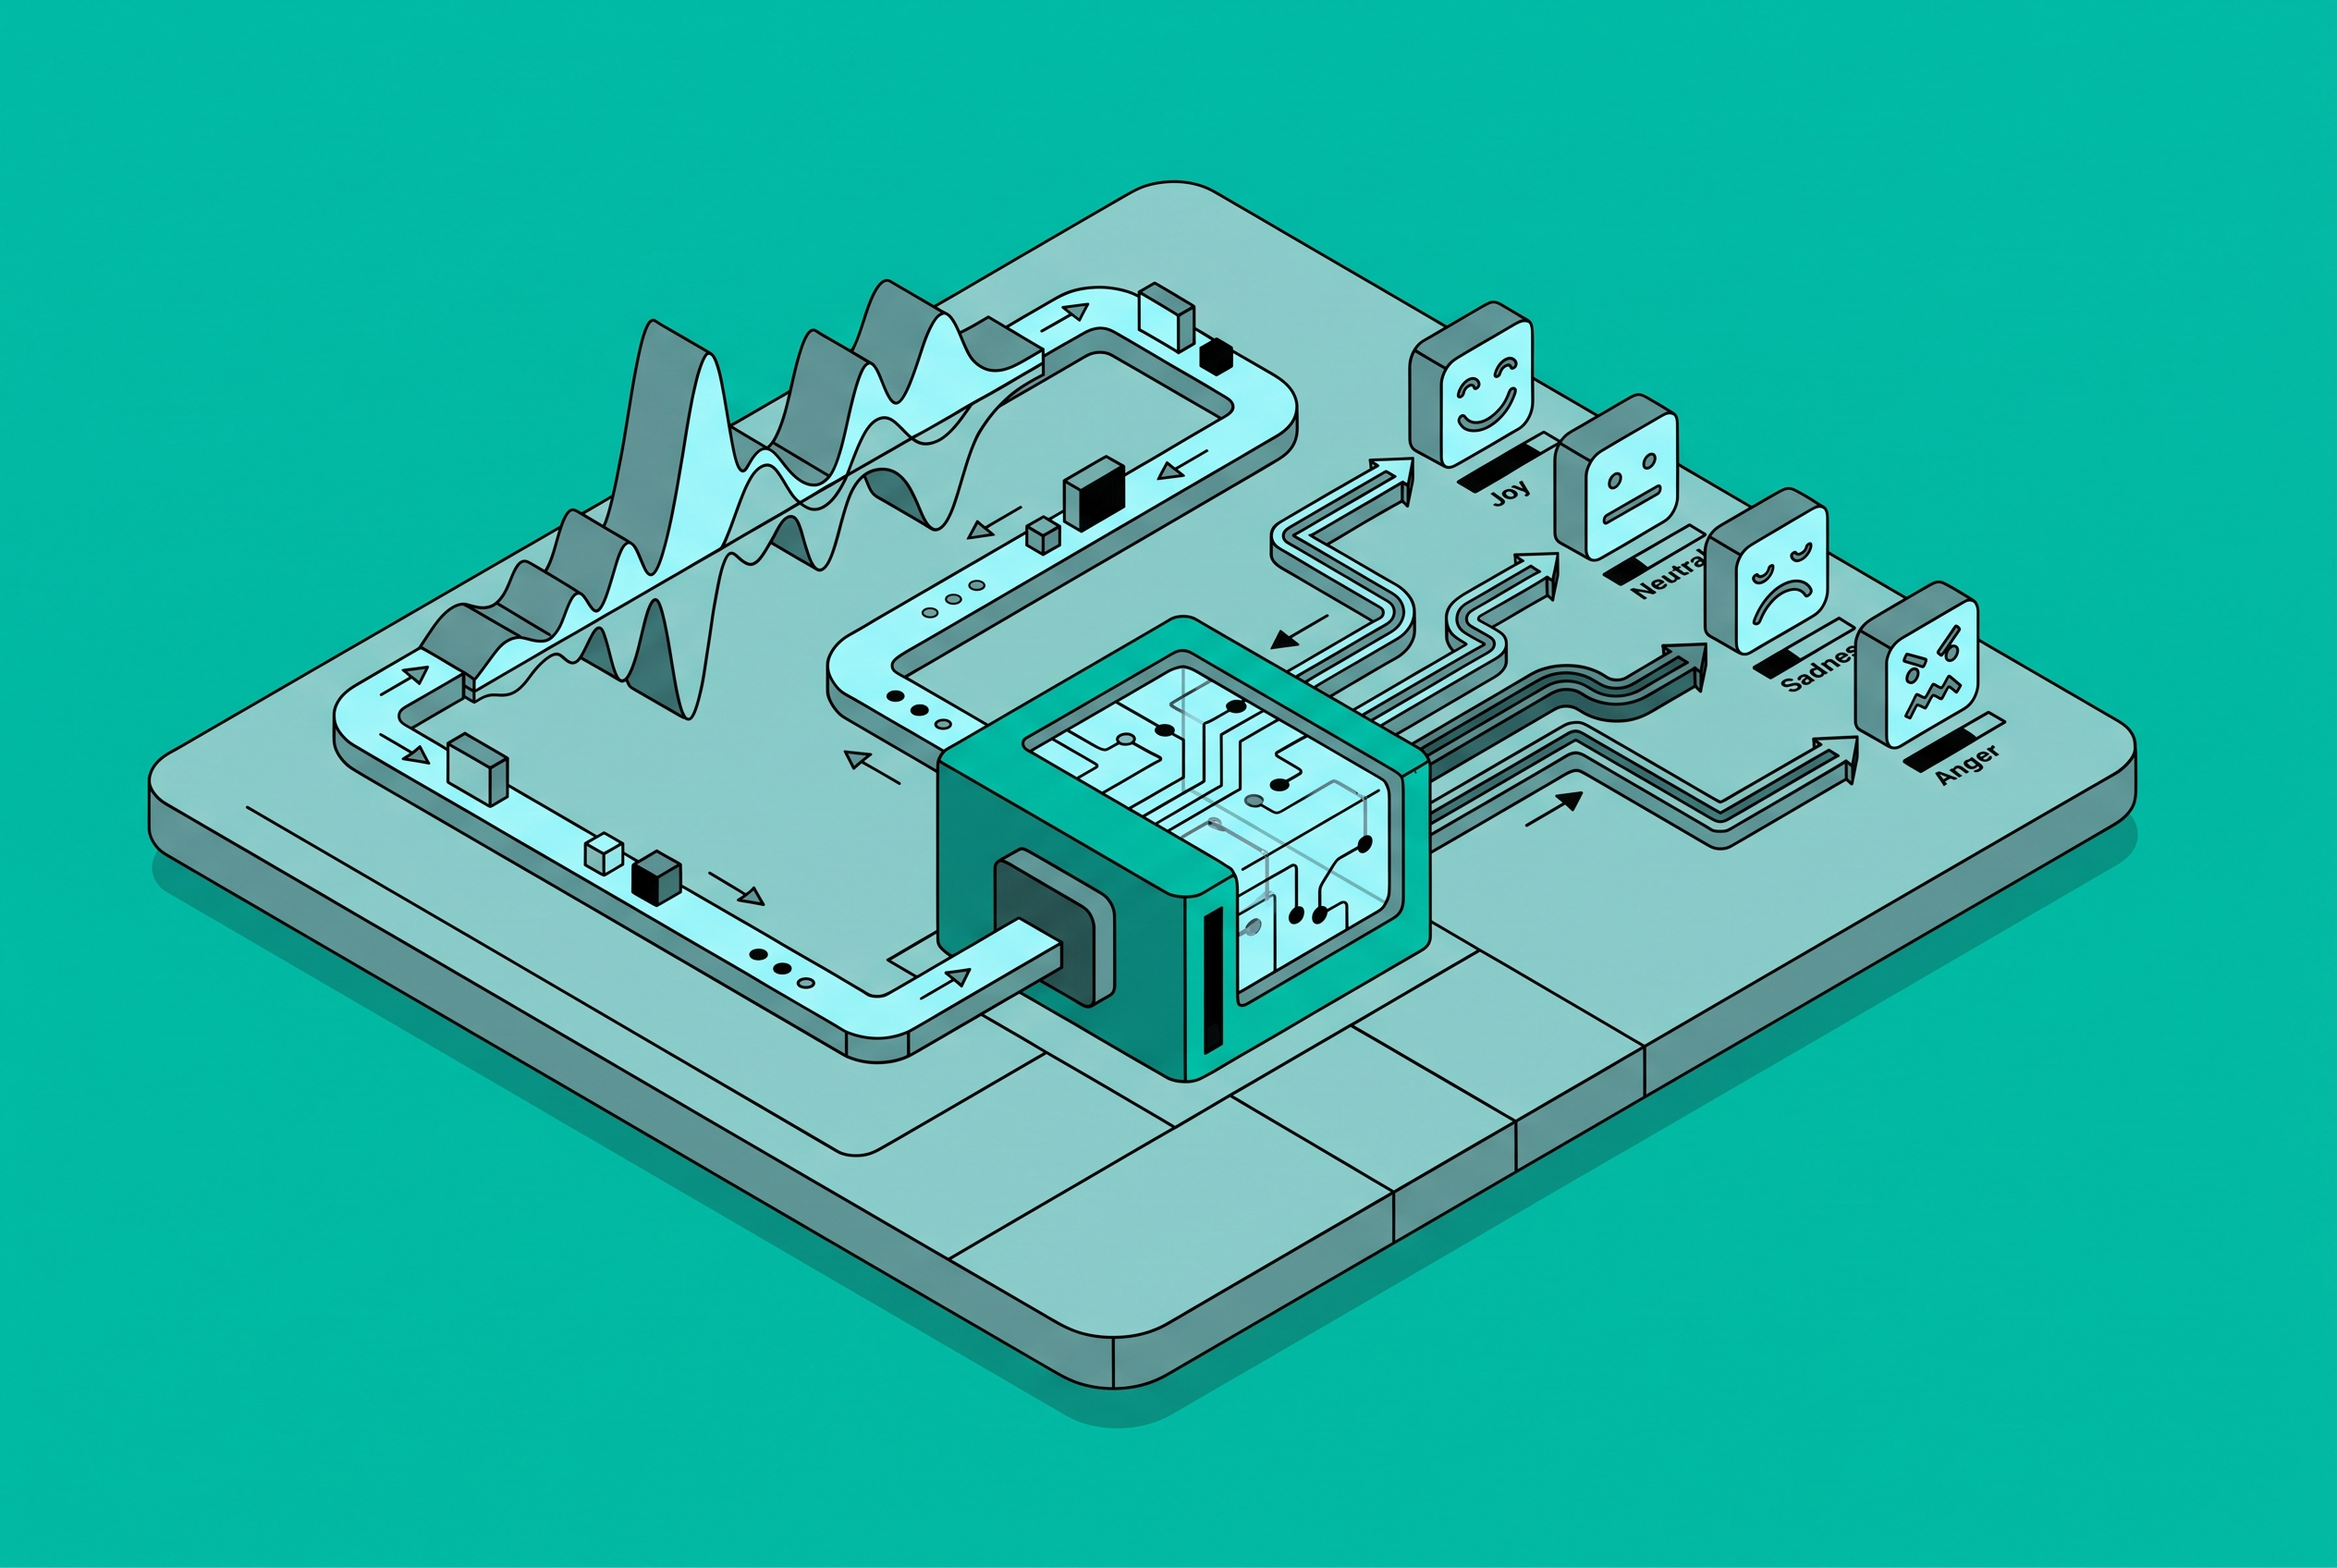
- Define the output: on a rolling window, a typical system emits a polarity label (negative / neutral / positive), an optional emotion category (frustration, confusion), and a confidence score — updated every few seconds while the call is live
- Two input streams, not one:
- Lexical — the words, recovered by speech recognition
- Acoustic — prosody: fundamental frequency, energy, speaking rate, voice quality, pause placement
- Why both matter: text alone misreads sarcasm and flat resignation; prosody alone misreads an animated but satisfied caller — the combination is what makes output usable
- A third input often left out: conversational context — the same sentence carries different weight in the opening ten seconds than it does after the caller has repeated their account number three times
- Three labeling schemes in use, each with different tradeoffs:
- Categorical (Ekman's six basic emotions plus neutral) — easy to explain, weak on blended states like "frustrated but polite"
- Dimensional (valence, arousal, dominance as continuous scores) — better for nuance; "angry" and "excited" are both high arousal but opposite valence
- Fine-grained taxonomies — e.g., Hume AI's 48-class model including states like "stressed yet focused" or "confused"; impressive for personalization, proprietary, harder to audit for bias
- Establish clearly: the score itself is not the product — what fires on that score (an agent prompt, a supervisor alert, a routing change) is where the value lives
The four pipeline stages where the engineering actually happens
- Stage 1 — Audio capture and noise handling:
- Contact center audio typically arrives at 8kHz, compressed, often with background noise and packet loss
- Everything downstream inherits whatever this stage produces — models trained on clean wideband audio degrade sharply on telephony; this is the single most common reason a pilot scores well in testing and disappoints in production
- Stage 2 — Transcription:
- Speech recognition converts audio to text; its error rate sets a ceiling on the lexical half of the analysis
- Accents, background noise, and multiple speakers compound the error — each one is an independent accuracy penalty
- Distinguish ASR accuracy from downstream emotion accuracy — they are separate failure modes often conflated in requirements documents
- Stage 3 — Prosodic feature extraction (runs in parallel with transcription):
- Pitch contour signals agitation; energy signals emphasis and withdrawal; speaking rate carries urgency
- Voice quality picks up strain a caller is trying to keep out of their words
- Pause structure — the length of the gap before a reply — is often one of the strongest signals and the least discussed
- Stage 4 — Fusion and scoring:
- A fusion model combines the lexical and acoustic streams into a single label and confidence score
- The model architecture choices (embedding type, fusion head design) made at this stage drive most of the accuracy variation across vendors
- Score update cadence is every few seconds on a rolling window — fast enough to act on, slow enough to avoid false spikes on a single word
Where accuracy numbers come from and why production performance looks different
- Open with the gap: research shows deep learning models reach more than 90% accuracy on benchmark datasets, with some architectures achieving up to 98% for core emotions such as happiness and anger (per gnani.ai); production performance depends on noise, accents, and channel quality — and routinely doesn't
- The benchmark that most vendor claims reference: IEMOCAP — acted emotion, clean conditions, a flattering dataset; fine-tuned wav2vec2/HuBERT models reach approximately 73% weighted accuracy on IEMOCAP speaker-independent benchmarks (per Fora Soft's 2026 playbook)
- What happens when those models hit real call-center audio: accuracy falls to 55–65% — a gap of roughly 8 to 18 percentage points before any domain fine-tuning
- Fora Soft's framing is worth carrying verbatim for the writer: "audio emotion detection is solved in the lab and broken in the wild" — benchmark numbers should be treated as marketing, not as product specifications
- Cultural and linguistic dimensions compound the gap:
- Japanese speakers may express emotions subtly; Italian speakers more expressively — AI systems trained predominantly on one pattern misread the other
- Advanced models now process 100+ languages (per VoiceGenie's feature set) and incorporate diverse training data, but training data limitations remain: systems perform best on the languages and cultural contexts well-represented in their datasets
- Per Schuller & Schuller (Proceedings of the IEEE, 2021): real-world performance typically drops to 60–75% due to cultural variability, background noise, and individual expression differences
- Key implication for practitioners: ask vendors which dataset produced their headline accuracy number, then test on your own call audio before treating any figure as a specification
Why multimodal fusion is now the baseline, not a premium feature
- Fusion's core contribution: combining voice and transcript sentiment adds approximately 8 percentage points of accuracy over voice alone in a 2025 five-class benchmark (per Fora Soft)
- Peer-reviewed 2025 results on a 5-class emotion task: multimodal architecture achieved 0.83 accuracy versus 0.75 voice-alone and 0.78 text-alone — the ceiling is meaningfully higher than either input stream independently
- What fusion actually enables that voice alone cannot: the difference between "detects arousal" and "knows your customer is frustrated" — arousal is high energy, frustration is high arousal plus negative valence plus context, and text is what supplies the valence signal
- Fora Soft's 2026 assessment: multimodal fusion on a fine-tuned backbone is the 2026 baseline — anything less is a prototype
- Practical note for the writer: fine-tuning on in-domain data is the other half of closing the production gap — a general-purpose fusion model on telephony audio starts at 55–65% until fine-tuned; domain-specific fine-tuning is where the usable production number is recovered
- Conversational context as the under-discussed third layer: the same sentence weighted differently depending on where it falls in the call — systems that ignore call position are leaving signal on the table
Where the score becomes action: the agent assist, alert, and routing layer
- Core point: a score that nobody acts on is a dashboard; the action layer is where sentiment becomes operational
- Three standard action types:
- Agent-facing prompt — suggested response surfaced in real time ("show empathy," "offer a resolution") based on detected frustration or confusion
- Supervisor alert — flags calls where sentiment crosses a threshold, enabling live intervention before a caller disconnects
- Routing change — escalation to a human agent when AI confidence in sentiment is high and complexity or emotional sensitivity warrants it
- Outcome evidence: voice agents that recognize subtle tones, urgency levels, and frustration reduce escalations by 25% (per nextlevel.ai)
- Consumer routing preference is nuanced and matters for how thresholds are set:
- 28% of consumers prefer AI over human agents for simple tasks, citing speed and no hold time (Zendesk CX Trends, 2026)
- 73% prefer a human agent for complex or emotionally sensitive issues — but 68% of those say they are fine with AI handling initial triage before transfer (Qualtrics XM Institute, 2025)
- Implication: the routing threshold should be calibrated to the issue type, not set globally
- Audit trail note: in regulated contact centers, the action layer needs a log of what fired and why — not a nice-to-have, because a compliance question about why a particular call was escalated requires a defensible answer
- Aggregated sentiment data across calls has a secondary value: identifying recurring pain points in products or services at scale, which is a different kind of output than the per-call action layer
Build vs. buy: what the cost and control tradeoffs look like in practice
- Managed API path:
- Hume EVI's 2026 tiers: $70/month for 1,200 EVI minutes on Pro; $0.06/minute overage on Pro; $0.04/minute overage at Business tier; sub-300ms latency; 48-class emotion taxonomy
- What managed buys: speed to deployment, zero MLOps overhead, access to a maintained model
- What managed costs: at hundreds of thousands of minutes per month, managed costs reach several thousand dollars a month
- Self-hosted path:
- Self-hosted wav2vec2 pipelines with fusion are several times cheaper per minute at scale (per Fora Soft)
- What self-host buys: cost control at volume, data sovereignty, ability to fine-tune on proprietary call audio
- What self-host costs: MLOps capacity, time to domain fine-tuning, ongoing model maintenance
- VoiceGenie as a mid-market reference point: detects tone and sentiment, supports 100+ languages, adaptive empathy and voice cloning, starting from approximately $50/month — a different tier than Hume, useful for illustrating that pricing varies by capability scope
- The decision heuristic: managed buys speed and zero MLOps; self-host wins on cost and control at scale — the crossover point depends on call volume and how much domain fine-tuning the use case requires
- One factor that shifts the calculus entirely: regulatory jurisdiction — covered in the next section, it can constrain the data handling model regardless of cost preference
What the EU AI Act actually prohibits and what it merely regulates
- The hard prohibition:
- Agent-facing "wellbeing dashboards" that read emotional state from voice data are banned outright across the entire EU under Article 5(1)(f) of the EU AI Act, in force since February 2, 2025 — not restricted, not regulated: banned
- Fines: up to €35 million or 7% of global turnover
- Three EU works councils publicly challenged employer emotion AI deployments in 2025, generating press coverage, employee relations damage, and board-level scrutiny — enforcement is not theoretical
- The customer-facing path — high-risk, not banned:
- Customer emotion AI was classified under Annex III, Category 4, as a "high-risk" system — permitted, but regulated
- Since August 2, 2026, the EU AI Act's general transparency rules apply; the stricter Annex III requirements are currently scheduled from December 2, 2027
- Article 50(3) requires deployers to inform natural persons exposed to an emotion recognition system (subject to an exemption for systems lawfully used to detect, prevent or investigate criminal offences) of its operation — not a privacy policy footnote, but clear and meaningful notice before analysis begins
- Relative stability: the European Commission's November 2025 proposals did not propose changes to the prohibited practices or emotion recognition provisions, so the current framework is expected to hold
- Enforcement geography: France's CNIL is specifically targeting recruitment use cases; Germany and Ireland enforcement machinery is also active; employees can file with both the data protection authority and the AI Act market surveillance authority simultaneously — two separate investigation tracks
- Data classification reminder: voice emotion data is biometric data under GDPR and PHI under HIPAA in the US — legal surface design should precede model selection
- US contrast: no blanket ban, but EEOC guidance is tightening, and voice emotion alone is too unreliable to survive a disparate-impact challenge — a different risk profile but still a constraint on high-stakes automated decisions
Where the technology reliably delivers and where it still falls short
- Where performance is robust:
Methodology & sources
- How to Implement Audio Emotion Detection with AI: 2026 Playbook
Supplied the IEMOCAP versus call-center accuracy gap, the fusion gain, the 2026 baseline claim, and self-hosted cost comparisons.
- Real-Time Voice Sentiment Analysis with AI: Understanding and Responding to Emotion as It Happens
Informed the description of real-time sentiment output and how detected emotion triggers agent prompts and supervisor alerts.
- How Real Time Sentiment detection Works in Voice AI
Provided the benchmark accuracy claims of over 90% and up to 98% for core emotions, and the pipeline explanation.
- 7 Ways AI Reads Your Emotions Through Voice [2025 Study]
Supported the section on cultural differences in emotional expression and the drop in real-world accuracy.
- Call Center AI Market Size, Share, Growth | Global Report [2034]
Source of the call center AI market size and projection figures ($2.41 billion in 2025 to $13.52 billion by 2034).
- https://arxiv.org/html/2506.09827v1
Peer-reviewed 2025 multimodal emotion benchmark underlying the fusion accuracy comparison against voice-alone and text-alone.